AI’s Next Data Source Is Your Business: The Privacy Questions Behind the Training Data Market
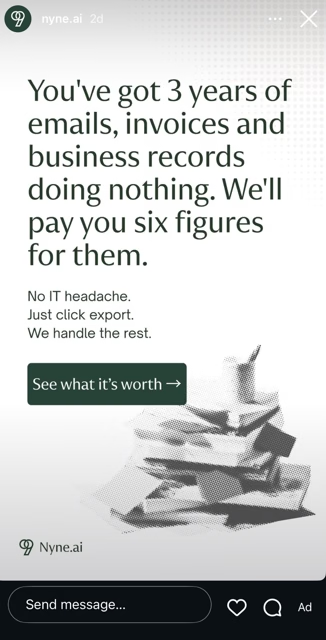
An advertisement makes the proposition unusually clear: “You’ve got 3 years of emails, invoices, and business records doing nothing. We’ll pay you six figures for them.”
For a business sitting on years of operational records, the offer can sound like an opportunity to monetize an overlooked asset. For the employees, customers, and others described in those records, the transaction raises a different question: when did information used to run a business become material for training someone else’s artificial intelligence?
The emerging market for private business data brings that question into focus. It also connects several areas of privacy law that businesses sometimes address separately: the sale of personal information, data broker regulation, privacy policy commitments, and the purchaser’s responsibilities after receiving a dataset.
Why AI companies want data beyond the public internet
The explanation requires more nuance than saying AI companies have already trained on the entire internet. Public information continues to grow, training practices vary, and synthetic data and other techniques can support further development. Epoch AI’s research on training data availability nevertheless identifies potential limits to continued scaling using human-generated public text. Those projections concern a particular category of data and depend on assumptions about how models develop.
Private business records offer something different from another collection of public webpages: examples of work unfolding over time. An invoice connects to a customer request, an approval, a payment dispute, and an eventual resolution. Project records show how employees identify problems, delegate tasks, and complete them. That context can be useful for systems intended to perform business tasks.
Nyne’s company data licensing page illustrates this demand, identifying accounting records, customer relationship management systems, support histories, scheduling, and project management data. The company describes anonymization, defined uses, and contractual controls. Its advertised compensation is a marketing proposition, rather than a guarantee that any particular business will receive that amount. The privacy questions discussed here concern this market generally; an advertisement alone does not establish unlawful conduct.
Spirit Airlines shows why the transaction matters
Google’s proposed purchase of Spirit Airlines’ business data provides a prominent example. Google won an auction with a $10 million bid for data intended to help improve its products and AI models. This is a transaction involving data assets, rather than an acquisition of the airline. Reuters reported that lawmakers raised concerns about employee records and communications, while Google said personal information would be excluded or de-identified by an independent third party before receipt.
According to Stretto’s analysis of the bankruptcy filings, the proposed transaction was narrowed to exclude structured passenger databases, with independent deidentification of remaining unstructured material. The consumer privacy ombudsman recommended approval from a consumer privacy perspective, but expressly did not investigate risks to employees or third parties. The report also describes vendor objections involving proprietary information.
The transaction remained proposed as of this article’s date. Travel Weekly reported that the approval hearing was postponed to November 6, 2026.
The distinction between passenger and employee information is consequential. Removing a customer database does not necessarily resolve the privacy issues in employee communications, attachments, or operational systems. Nor does removing identifying details necessarily resolve contractual confidentiality or proprietary rights. A single archive can contain several kinds of information subject to different legal restrictions.
Possessing business records does not establish permission to sell them
Consider a company offered payment for three years of email and customer support records. Its systems may contain employee medical leave discussions, customer complaints, confidential vendor documents, and information supplied on behalf of someone else. The company’s authority to retain those records for its operations does not itself answer whether it may disclose them for an unrelated training purpose.
The first review should therefore address the records’ origin, the people involved, the purposes for which information was obtained, and applicable restrictions. Relevant documents can include historical privacy notices, customer agreements, employment notices, confidentiality agreements, and contracts governing data received from other businesses.
A particularly important distinction is whether the seller collected information for its own purposes or holds it on another organization’s behalf. A vendor cannot assume that access granted to provide a contracted service also authorizes a separate data monetization business (to the contrary, it generally does not allow for such monetization). The same inquiry belongs in data processing agreement reviews and AI vendor contracting.
In the United States, an AI training license can be a sale of personal information
Calling a transaction a license does not settle its privacy classification. A paid transfer of personal information for a buyer’s independent training purposes can fall within statutory sale definitions, even if the seller retains a copy and the buyer never uses the data for advertising.
The differences among state laws matter. California’s privacy regulator explains that a sale can involve monetary or other valuable consideration and that the former employee and business contact exemptions have expired. By comparison, Virginia’s Consumer Data Protection Act defines sale by reference to monetary consideration and excludes individuals acting in commercial or employment contexts from its definition of consumer. Its requirements also include consent for covered sensitive data processing. These differences can change which parts of a mixed business archive receive protection under a particular comprehensive privacy law.
California’s implementing regulations also constrain collection and use according to necessity, proportionality, reasonable expectations, and compatible purposes, with consent required for processing outside the permitted framework. Selling information for AI training therefore requires more than deciding whether an opt-out link belongs on the seller’s website.
Each party’s coverage, the individuals’ locations, applicable exemptions, and the actual data flow require review. An employment exclusion in one state’s comprehensive privacy statute also does not establish that employee information is unrestricted under every other law or agreement.
The purchaser has its own obligations
The buyer’s compliance analysis should begin before ingestion. A purchase agreement does not supply every permission needed to collect, combine, retain, train on, or redistribute personal information.
Under California’s CCPA, collection expressly includes buying and receiving personal information. The statute also restricts a recipient’s subsequent sale or sharing without explicit notice and an opportunity to opt out. The third-party contract regulations require specified purposes, applicable privacy protections, and oversight and remediation rights. A third party without the required contract cannot simply proceed with using the information.
For the purchaser, the practical questions include whether its notices cover people whose information came from another company, whether the proposed training fits the authorized purpose, and how restrictions will follow the data into subsequent datasets and recipients. A representation that the seller “owns the data” leaves those questions unresolved.
Bankruptcy and acquisitions do not erase privacy restrictions
Spirit also illustrates why the structure of a transaction matters. Comprehensive privacy statutes can exclude qualifying transfers in mergers, acquisitions, or bankruptcy from their definition of sale. That exclusion is different from a general exemption for the purchaser’s later processing.
California’s transaction provisions preserve compliance requirements, address materially inconsistent new uses, and require covered transferees to honor sale and sharing opt-outs directed to the transferor. Businesses should examine whether the particular deal qualifies and what obligations continue afterward. A standalone training data license should not automatically be treated like the acquisition of an operating business.
When does the AI data market become data brokering?
A business entering this market may also need a data broker compliance assessment. Buying data alone does not automatically make a company a data broker under every registration law. The analysis can change when it assembles, licenses, or resells personal information concerning people with whom it has no direct relationship.
California’s Delete Act defines a data broker by reference to a covered business knowingly collecting and selling personal information about consumers with whom it lacks a direct relationship, subject to exemptions. An intermediary may have a direct commercial relationship with a company supplying records while lacking any direct relationship with the individuals in those records.
The consequences extend beyond registration. California’s DROP requirements require data brokers to access the platform at least every 45 days and process deletion requests, subject to exceptions. Training data businesses should assess how those requirements affect source records, inferences, future collection, and downstream arrangements.
AI Can Make Purchased Data More Revealing
The privacy implications extend beyond using purchased records to train a model. AI can also make existing commercial datasets easier to search, connect, and interpret, potentially revealing information that no individual source disclosed on its own.
In “The Feds are buying your data. AI is making it more useful than ever,” Coin Center examines how the commercial data market can supply information for government surveillance, with AI increasing the usefulness of those records. The concern builds on documented government purchasing practices: documents released by Senator Ron Wyden confirmed that the NSA purchases Americans’ internet browsing records.
This raises a related question for businesses selling or licensing data: what can a recipient discover by combining the records with information it already holds? A dataset that appears relatively limited in isolation may become substantially more revealing when linked to location histories, public records, photographs, or other commercial sources. Training, identity resolution, profiling, and investigative analysis are different activities and should be evaluated separately.
For businesses, the practical implication is that diligence should examine downstream uses and recipients, including onward licensing and access by government customers. Restrictions on reidentification, dataset combination, and permitted purposes should address the actual capabilities involved. A transaction described broadly as supporting “AI development” leaves important questions unanswered about how the information may ultimately be used.
Under the GDPR, purchasing data does not supply a lawful basis
Where the GDPR applies, the analysis centers on the lawfulness of each processing activity. The seller’s disclosure and the purchaser’s training use both need justification. A contract between those companies does not, by itself, authorize processing information about the people described in the records.
France’s CNIL addresses this directly in its guidance on reusing data for AI development. It distinguishes information originally collected for training from information repurposed after collection for another reason. It also calls for purchaser verification and explains that a clause requiring a supplier to obtain consent does not itself prove that valid consent exists.
Consent is not necessarily the only possible basis. The European Data Protection Board’s Opinion 28/2024 recognizes that legitimate interests may support AI development or deployment in appropriate circumstances. Its assessment requires identifying the interest, testing necessity, and balancing that interest against individuals’ rights and freedoms. A commercial benefit alone does not complete that analysis.
A purchaser should be prepared to explain why the particular personal data is needed, what less intrusive alternatives exist, and how the use relates to individuals’ reasonable expectations. The CNIL’s legitimate interests guidance provides further detail. Special category data, such as health information, raises additional Article 9 requirements; legitimate interests alone does not satisfy those requirements. CNIL’s guidance on legal bases also illustrates why consent for one use does not automatically authorize training.
These issues belong in the transaction’s GDPR assessment, along with territorial scope, security, retention, international transfers, and any required impact assessment. The location of a data supplier alone does not determine the answer.
The buyer’s privacy notice must address people it never signed up
A purchaser may have no account relationship with the employees or customers represented in its dataset. Its privacy notice still needs to address the processing that applies to them.
For indirect collection, GDPR Article 14 generally requires information within a reasonable period, no later than one month, with earlier deadlines for specified communications or disclosures. The CNIL’s AI transparency guidance explains that the seller’s notice only avoids a new notice obligation where individuals already received the full information about the purchaser’s processing. A disproportionate effort exception requires a documented assessment; it is not an automatic exemption for large datasets, and public information and appropriate safeguards remain important.
U.S. requirements also increasingly address training expressly. Effective July 1, 2026, Connecticut’s amended privacy law requires covered controllers’ notices to state whether they collect, use, or sell personal data to train large language models. The law separately addresses incompatible material new purposes and sensitive data. Disclosure should therefore be evaluated alongside the permissions required for the underlying activity.
For both sides, a useful privacy policy review should connect sources, categories, training purposes, recipients, retention, and usable rights procedures. A notice written only for website visitors may fail to explain a business model built on purchased records.
“Anonymized” needs technical and legal support
Deidentification can materially change the analysis, but a label is insufficient. Removing names from emails may leave unique job histories, unusual incidents, travel details, or combinations of facts that identify someone. Buyers should assess the released dataset and the information reasonably available to those who will receive it.
California’s deidentification definition includes reasonable measures against association with a consumer or household, a public commitment concerning deidentified use, and contractual obligations for recipients. It is more than a redaction exercise.
The dataset and the trained model also require separate consideration. The EDPB’s AI model opinion rejects a blanket assumption that models trained on personal data are anonymous. Relevant considerations include the likelihood of extracting personal data or obtaining it through queries. A claim that the eventual model will be anonymous does not itself justify the earlier collection and training operations.
Confidentiality requires another review. A document can lose its personal identifiers while retaining a counterparty’s proprietary strategy or information subject to contractual restrictions. The work of establishing privacy compliance and the work of establishing permission to disclose confidential content overlap, but neither necessarily completes the other.
Changing the policy after the offer arrives is not a complete solution
A lucrative offer may prompt a business to revise a promise that information would only be used to provide its service. The timing and substance of that change matter.
In its guidance on AI and privacy policy changes, FTC staff warned that quietly expanding practices through retroactive amendments can be unfair or deceptive. The warning specifically discusses training and disclosures to third parties.
A revised notice can explain a lawful change. It does not automatically cure an earlier conflicting promise, obtain required consent, or establish that an unexpected new use is permissible. Historical versions of notices and consent records should form part of diligence.
OkCupid and Clarifai: When Dating Profile Data Becomes AI Training Material
The FTC’s action involving OkCupid and Match Group illustrates how information collected for one service can become valuable training material for an unrelated AI company. As discussed in our analysis of the OkCupid/Match matter, the FTC alleged that, in 2014, OkCupid gave Clarifai access to nearly three million user photos, together with demographic and location information. According to the FTC’s complaint, OkCupid’s founders were financially invested in the recipient. Clarifai paid nothing for the data, provided no services to OkCupid, and received access without a formal agreement restricting its use.
The problem was the conflict between that disclosure and OkCupid’s privacy promises. The FTC alleged that Clarifai did not fall within the categories of recipients identified in the policy and that users did not receive the promised notice and opportunity to opt out. The March 2026 enforcement action therefore centered on deceptive representations about data sharing. It demonstrates that privacy enforcement can arise even when information changes hands without a cash payment. Whether a particular transfer also constitutes a “sale” under a state privacy statute requires a separate analysis.
For businesses considering similar arrangements, the recipient’s actual role matters. An AI company obtaining records for its own model development should not automatically be treated as a service provider merely because the transfer involves technology. The purpose of the disclosure, the recipient’s independent uses, and the restrictions actually imposed must align with the company’s notices and applicable law. Signing an agreement after identifying a valuable dataset does not, by itself, resolve conflicting promises made when the information was collected.
The downstream consequences also deserve attention. Reuters reported in April 2026 that Clarifai certified to the FTC that it had deleted the data and separately told a lawmaker’s office that it had deleted models trained on that data. That reported deletion should be distinguished from the OkCupid/Match settlement itself, which prohibited privacy misrepresentations and imposed compliance obligations but did not expressly require Clarifai to destroy its models. Clarifai was not a defendant in that action.
The separate Everalbum settlement provides the more direct example of an express model deletion requirement: the FTC required deletion of models and algorithms developed using users’ photos and videos. Together, these matters show why diligence must consider both the source information and the trained assets created from it. They do not establish that every unlawful transfer automatically requires model destruction, but they demonstrate that the consequences can extend beyond deleting the original dataset.
Plan for rights requests before the data enters training
The parties should understand what they can do if someone later exercises an applicable access, correction, deletion, or objection right. That requires distinguishing source records, prepared training datasets, and any personal data retained in a model.
The CNIL’s guidance on rights in AI development recognizes different implementation problems for datasets and models. The obligations and available exceptions require a contextual assessment. Deleting a source file does not necessarily remove its influence from a model, while every deletion request does not automatically require retraining an entire model.
What businesses should resolve before signing
Practical diligence should produce answers that engineering, compliance, and commercial teams can implement:
- Identify the actual package. Determine which systems, attachments, fields, individuals, and jurisdictions are involved. Inspect representative samples through an appropriately restricted process before authorizing a broad export.
- Establish authority and provenance. Review collection history, notices, consent evidence where relevant, customer restrictions, and third-party rights. Identify records that must be excluded.
- Define the permitted activity. Distinguish training, fine-tuning, evaluation, retrieval, and resale. Specify the models, recipients, and uses covered rather than relying on an undefined right to improve products.
- Set release conditions. Allocate responsibility for filtering, deidentification, testing, acceptance, and rejection. Determine who may access identifiable information during preparation and under what restrictions.
- Make downstream controls operational. Address security, retention, data broker laws, rights requests, suppression, onward transfers, incident cooperation, audit rights, remedies, and responsibility for resulting models when a problem arises.
The agreement should reflect the specific transaction. A working AI governance program should make data acquisition a reviewable decision before training begins.
The opportunity comes with continuing obligations
The value of operational data helps explain why businesses may receive offers for records they previously viewed as administrative overhead. It also makes the purchaser’s intended use central to the transaction.
Our view is that privacy diligence will increasingly influence the value of these deals: what can be transferred, which uses can be supported, and whether restrictions can be honored after delivery. A smaller dataset with documented permissions and workable controls may be more useful than a large archive carrying unresolved obligations.